Robotics · Reinforcement Learning · Sim-to-Real Transfer
Anubhav Singh
Reinforcement Learning Engineer working on learning-based robotic locomotion, hierarchical control, and robust sim-to-real transfer for real robots.
- Research Interests
- Research Projects
- Robotic Platforms
- Experience
- Education
- Patent
- Selected Projects
- Certifications
- Contact
- GitHub
- Stack Overflow
My work is driven by a strong interest in robotics, reinforcement learning, and the challenge of making learning-based controllers work reliably on real robots. I am particularly interested in legged locomotion, from quadruped robots to bipedal systems, and in developing controllers that produce stable, adaptive, and energy-efficient motion. While many learning-based methods perform well in simulation, deployment on real hardware introduces challenges such as modeling errors, sensor noise, actuator limitations, terrain variation, and changing environments. My goal is to address these challenges through reinforcement learning, system-level design, sim-to-real transfer, and hands-on robotic experimentation.
Most recently, I worked as a Reinforcement Learning Engineer at the BE2R Lab in Saint Petersburg, where my research focused on learning-based robotic locomotion and robust sim-to-real transfer. I worked on hierarchical reinforcement learning for structured gait and behavior generation, adaptive quadruped locomotion, energy-efficient movement, fall recovery, and the transfer of learned policies across simulation and real robotic platforms.
Research Projects
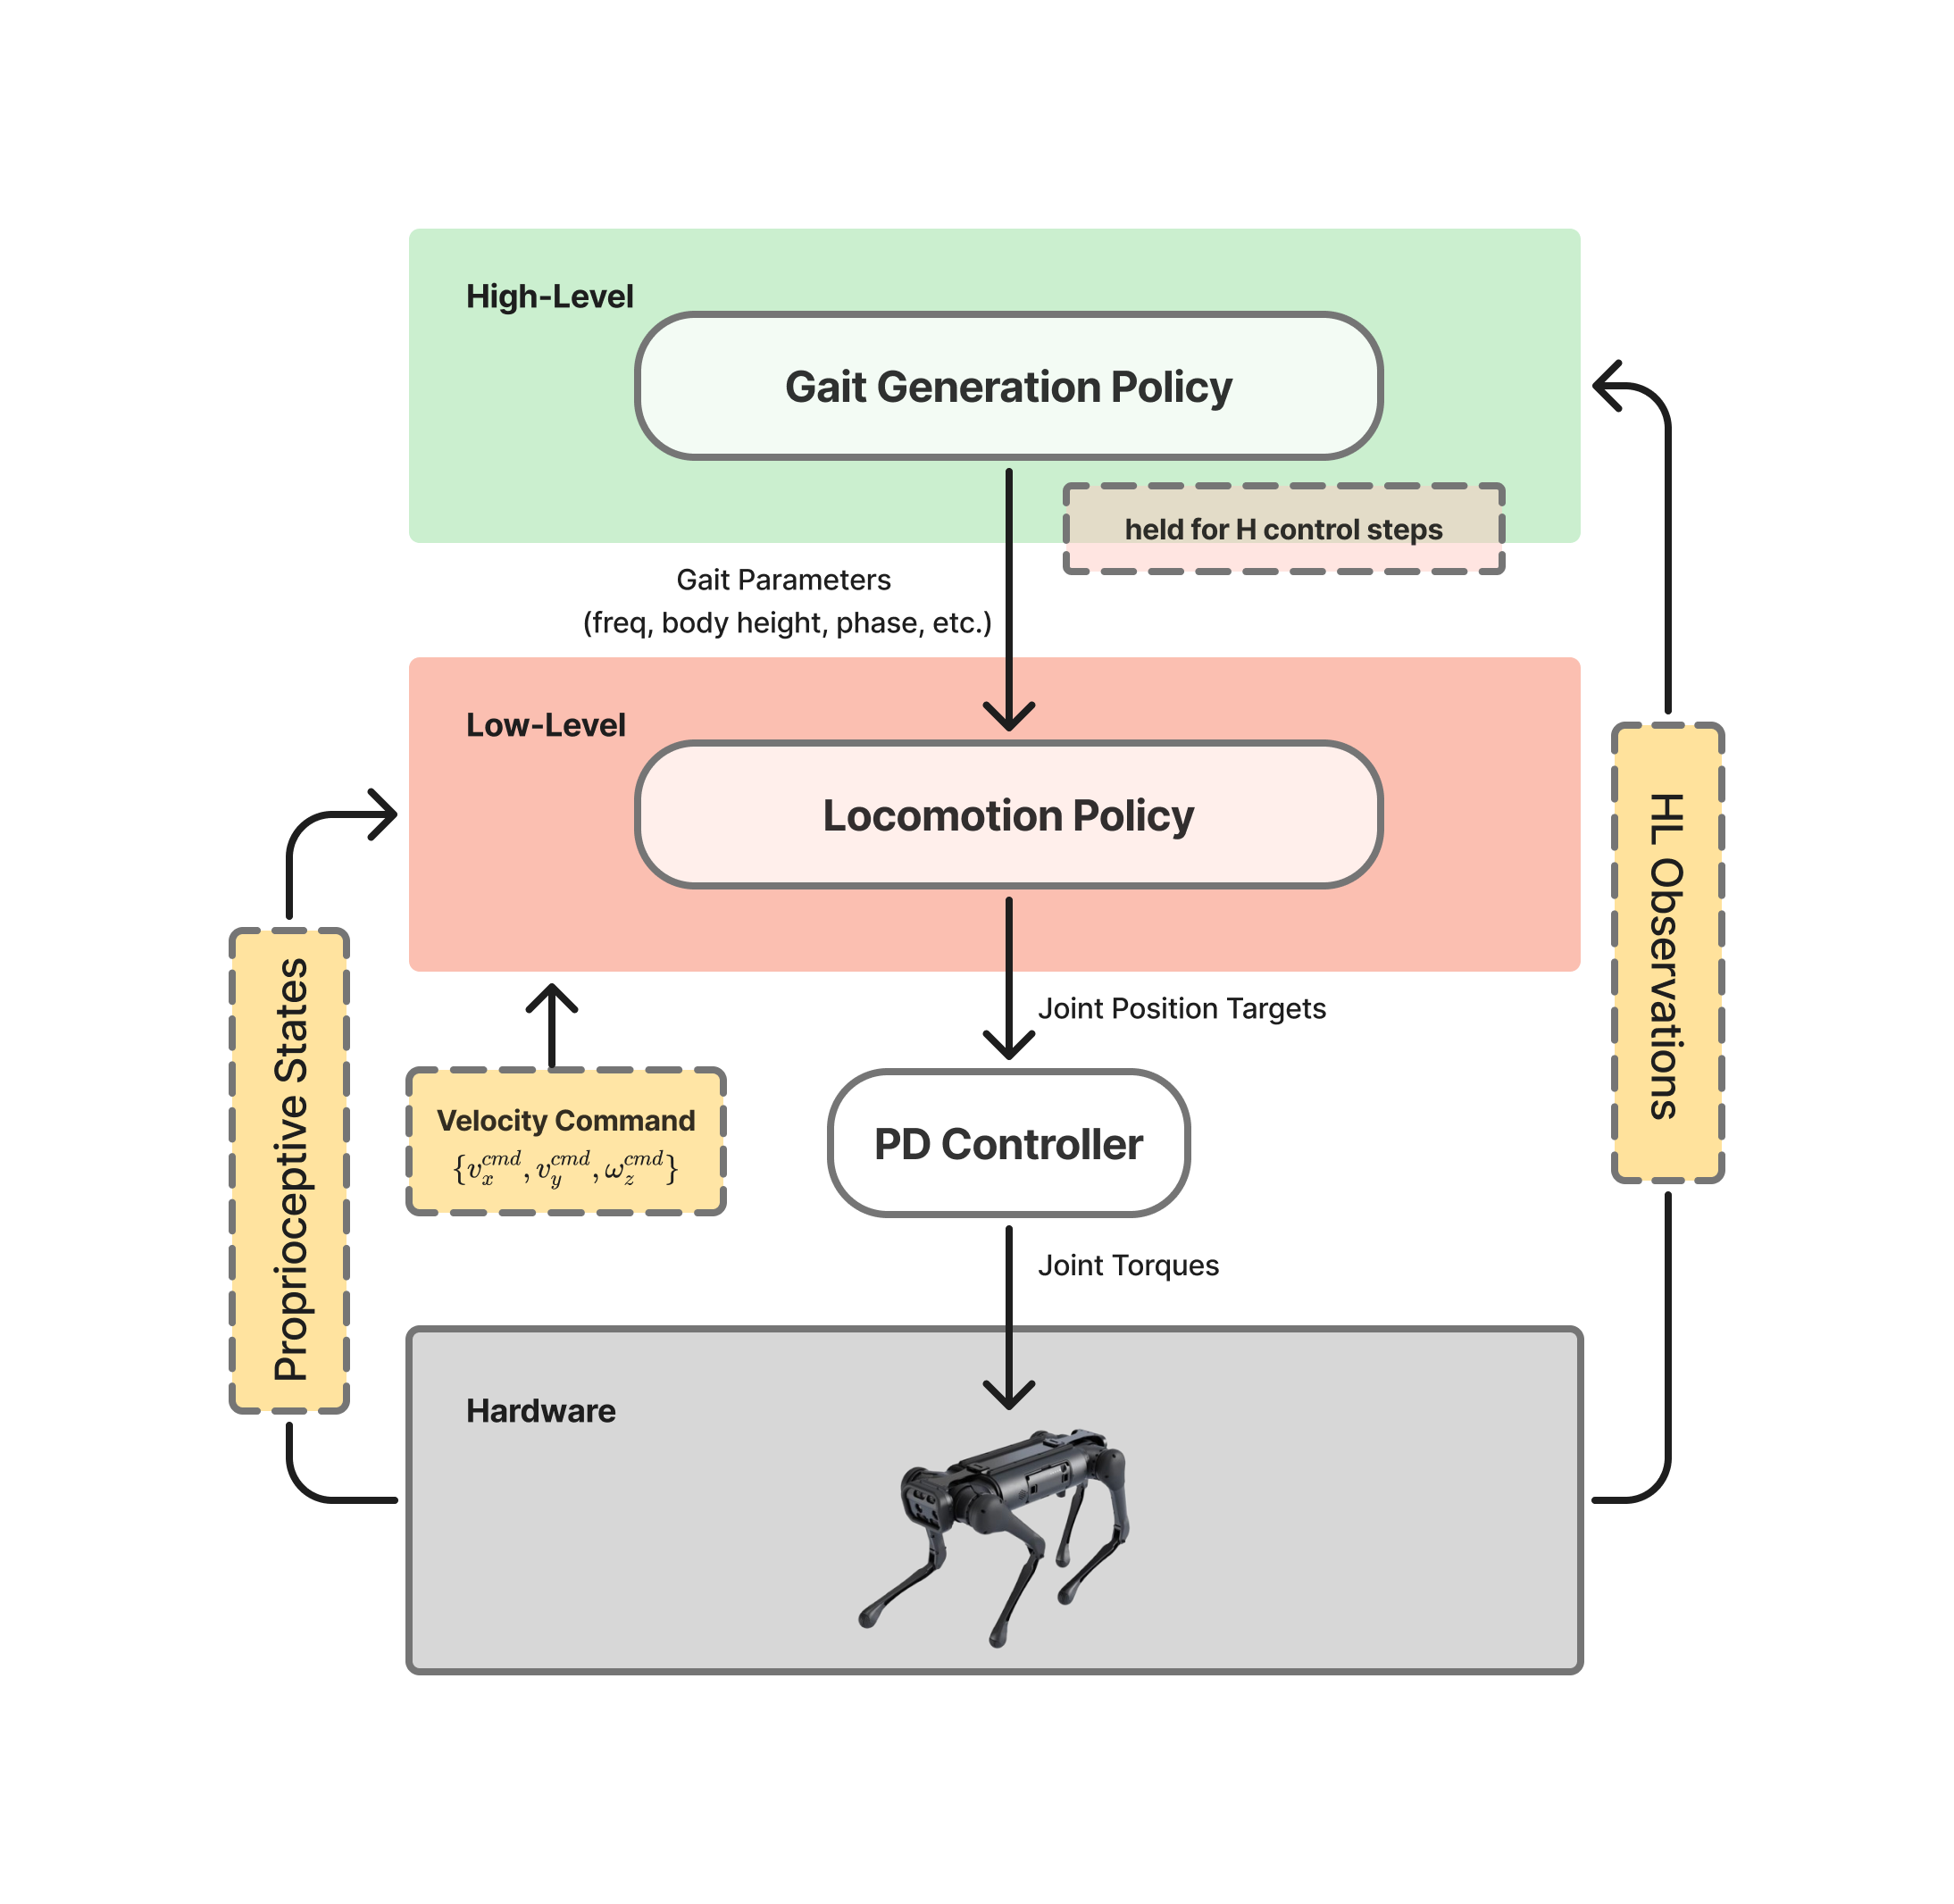
Learning Adaptive and Energy-Efficient Locomotion for Quadruped Robots via Hierarchical Reinforcement Learning
This research focuses on adaptive and energy-efficient locomotion for quadruped robots using a hierarchical reinforcement learning framework. The framework decomposes locomotion control across multiple time scales: a high-level policy generates smooth, energy-aware gait parameters, while a low-level controller tracks commanded velocities and maintains dynamic stability.
Policies are trained in the GPU-accelerated Isaac Gym simulator using massively parallel vectorized environments, evaluated in a MuJoCo-based simulation environment, and deployed on a Unitree AlienGo quadruped robot. Energy efficiency is measured using Cost of Transport.
Experimental results demonstrate that the proposed HRL framework outperforms fixed-gait controllers across all velocities and improves energy efficiency compared to end-to-end RL methods at intermediate and high speeds. The learned policy exhibits smooth, velocity-dependent gait adaptation without explicit gait scheduling.
View Full Project PageRobust Fall Recovery for Quadruped Robots Across Diverse Terrains Using Reinforcement Learning
This research project develops RL-based fall-recovery policies for quadruped robots operating on flat and uneven terrains. The objective is to enable the robot to recover from diverse fallen configurations and reach a stable standing posture without relying on manually scripted recovery motions.
The work began with a flat-terrain baseline in which the robot learned coordinated joint motions to recover from side-lying, supine, prone, and unstable intermediate configurations. It was subsequently extended to varied terrains, where differences in ground height, surface geometry, and contact conditions make reliable foot placement and stabilization more challenging.
A staged training strategy is used to first learn the general recovery motion and then improve support quality, stance geometry, velocity suppression, and terminal stability under randomized terrain and robot dynamics. The resulting policy is intended to improve quadruped resilience following locomotion failures, unexpected disturbances, and difficult environmental interactions.
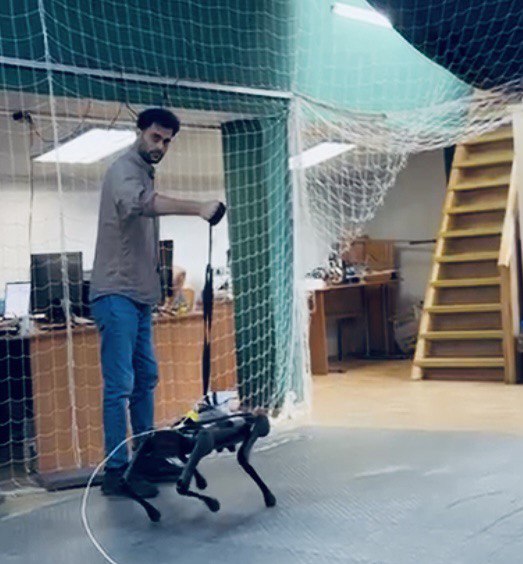
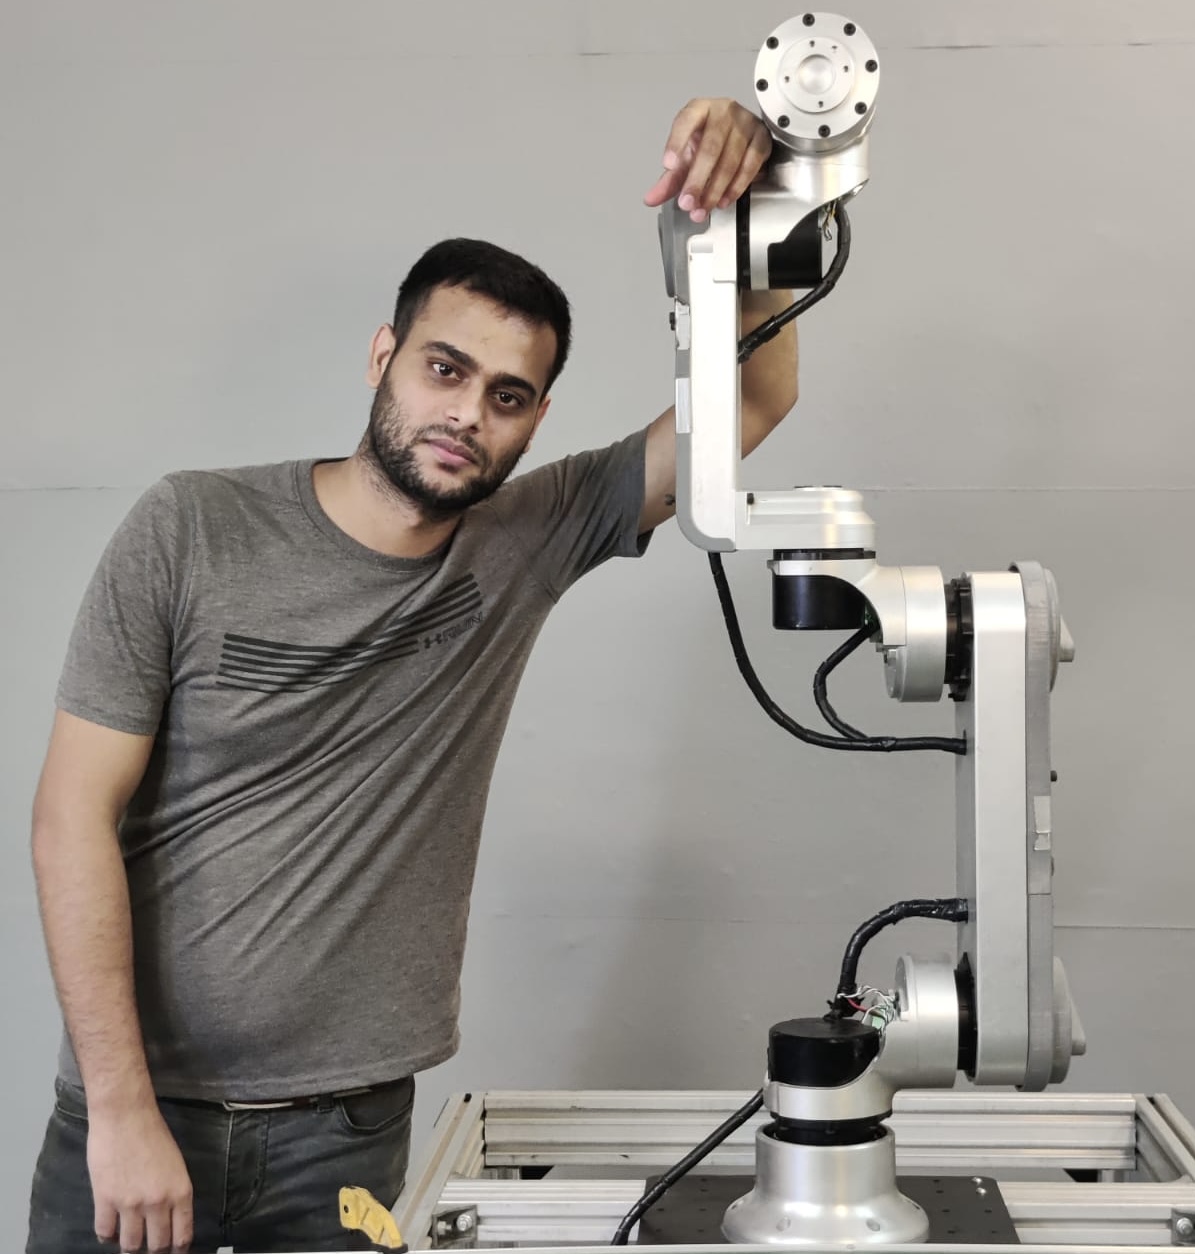
Robotic Platforms
Research & Engineering Experience
Biomechatronics and Energy-Efficient Robotics Lab
Reinforcement Learning Engineer
Working on learning-based robotic locomotion, hierarchical reinforcement learning, and sim-to-real transfer for quadruped robots, with emphasis on robust deployment, gait adaptation, and energy-efficient locomotion.
Orangewood Labs
Research and Development Engineer, AI & Robotics
Worked on robotic arm control, perception, motion planning, ROS-based software systems, and learning-based methods for improving robotic repeatability and transmission error compensation.
Lumiq.ai
AI Engineer Intern
Developed and deployed a machine learning model to classify smart-meter energy profiling charts as acceptable or anomalous, enabling real-time server-side assessment and supporting faster quality review of energy data outputs.
Education
M.Sc. in Robotics and AI
Mechatronics and Robotics
National Research University ITMO
Associated University Research Projects
- Learning-based perception and control for adaptive robots Fundamental Research Project · 2024 — 2025
- Machine learning methods for sensory processing and robot control in dynamic environments Applied Research Project · 2025 — 2026
- Embodied intelligence and software architectures for autonomous robot control Applied Research Project · 2026
B.Tech in Computer Science and Engineering
Patent
System and/or Method for Error Compensation in Mechanical Transmissions
Pending
Abhinav Kumar, Aditya Bhatia, Akash Bansal, Anubhav Singh,
Ashutosh Prakash, Aman Malhotra, Harshit Gaur, Prasang Srivasatava, Ashish Chauhan.
Orangewoodlabs Inc., Patent Application,
Publication Number WO/2021/211578, Publication Date 21.10.2021.
View patent application on PATENTSCOPE
Mechanical transmission mechanisms can enable systems to gear actuators up or down, but they can also introduce positional error in the system, negatively impacting performance. One example is backlash in gear systems. This patent application addresses the need for improved techniques to correct cumulative errors in mechanical transmission systems.
Selected Projects
Open Source Activity
GitHub Contributions
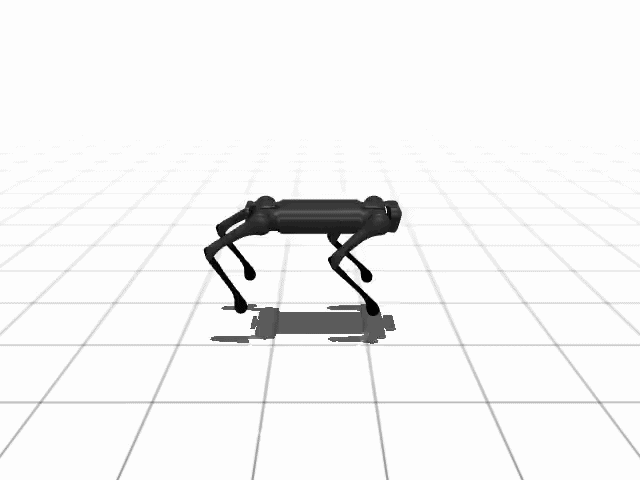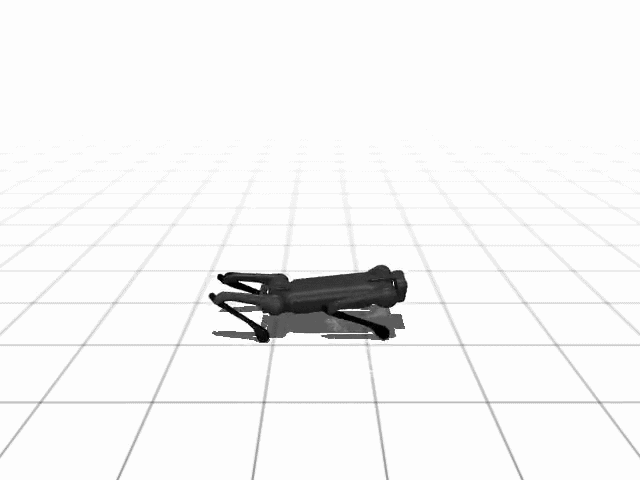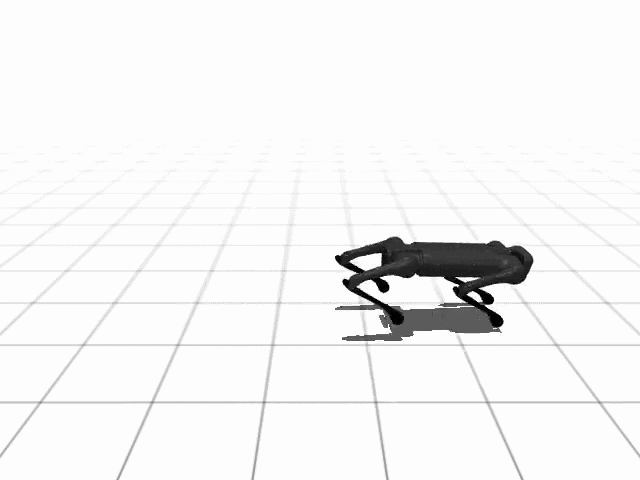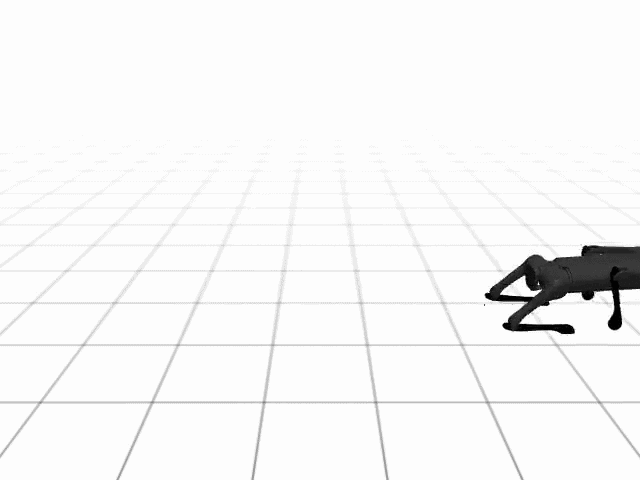
wtw-sim2sim-aliengo-mujoco
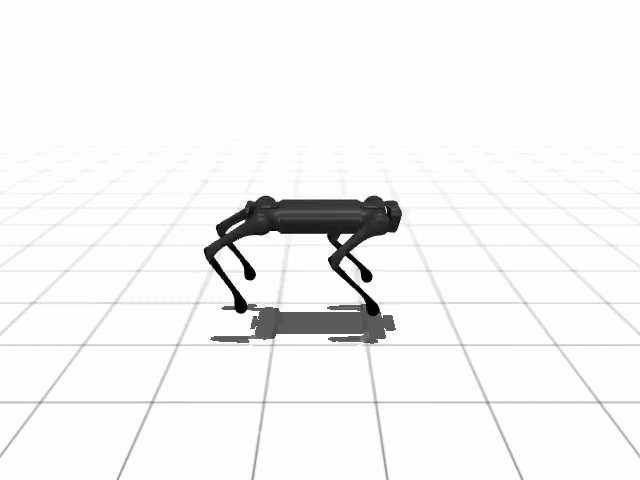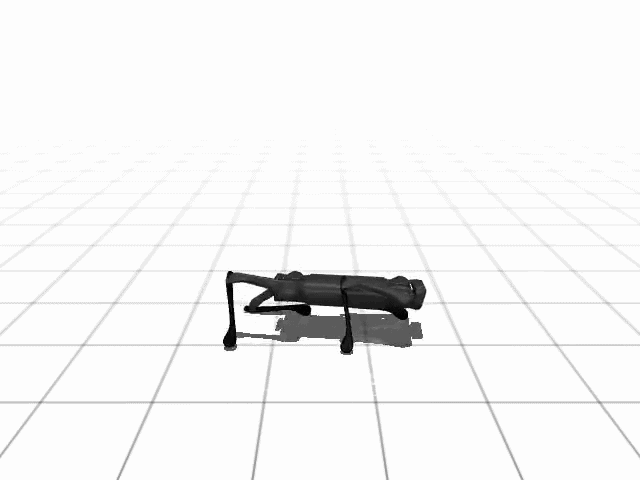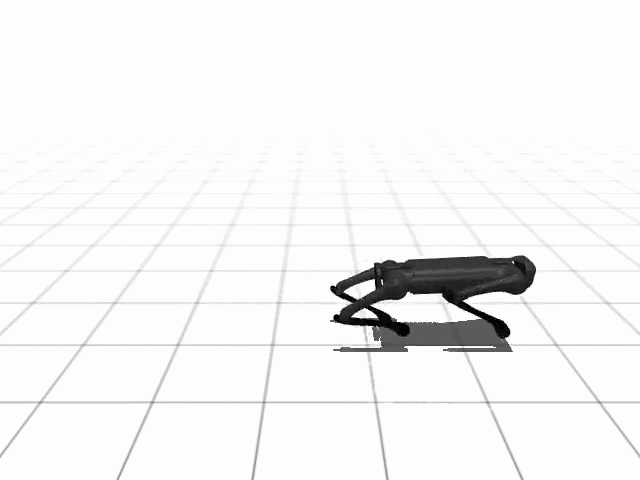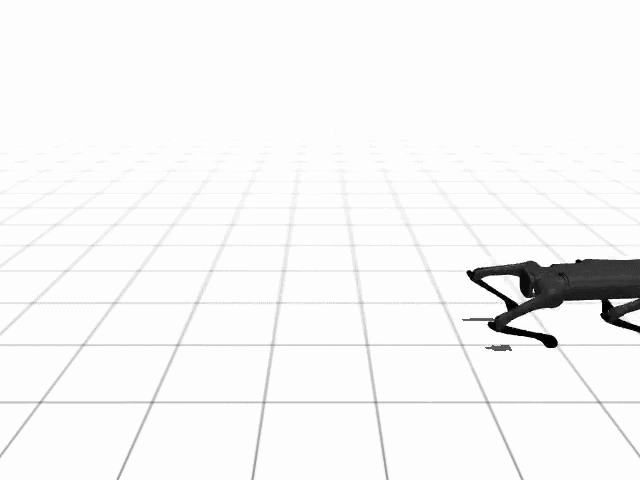
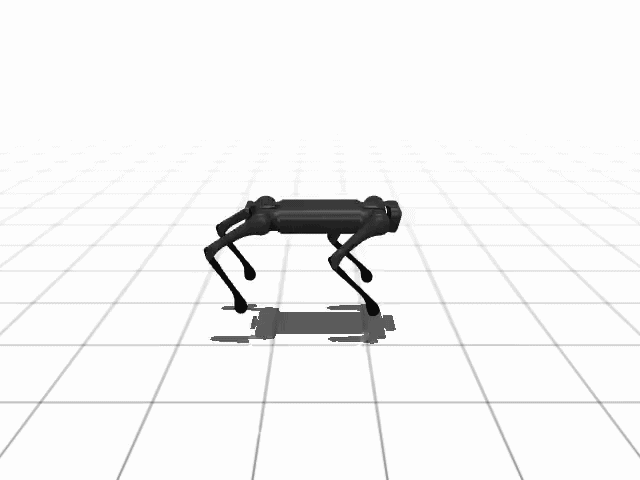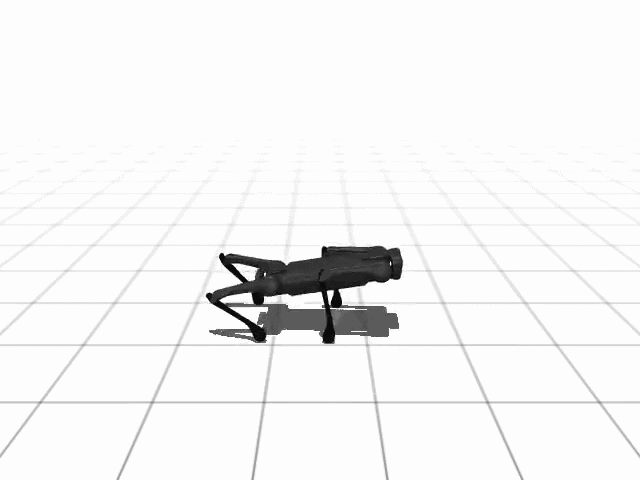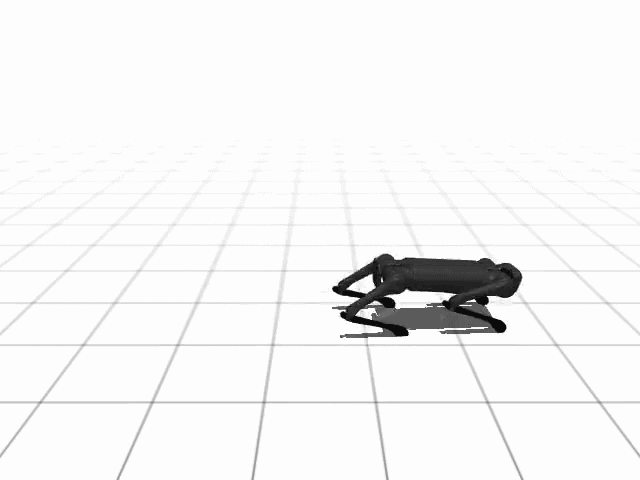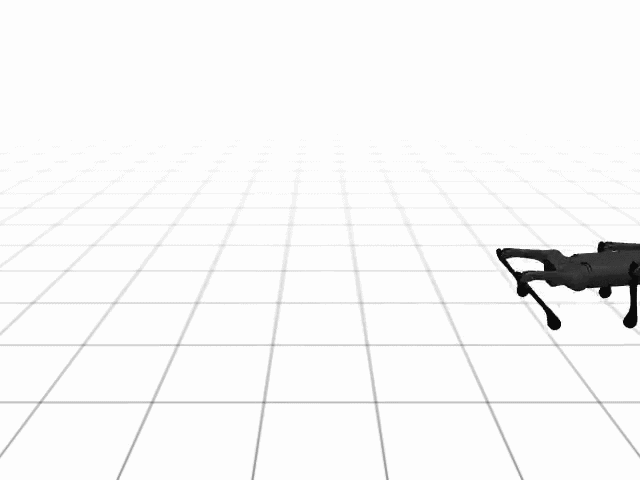
This project implements a MuJoCo-based sim-to-sim evaluation environment for AlienGo quadruped locomotion policies trained in Isaac Gym. It adapts the Walk These Ways locomotion pipeline from Unitree Go1 to AlienGo, while preserving history-based observations, lagged action execution, and PD-based torque control.
The project supports evaluation of gait-conditioned locomotion policies in a second physics simulator, helping analyze policy transfer, robustness, and sim-to-sim consistency before real-world deployment.
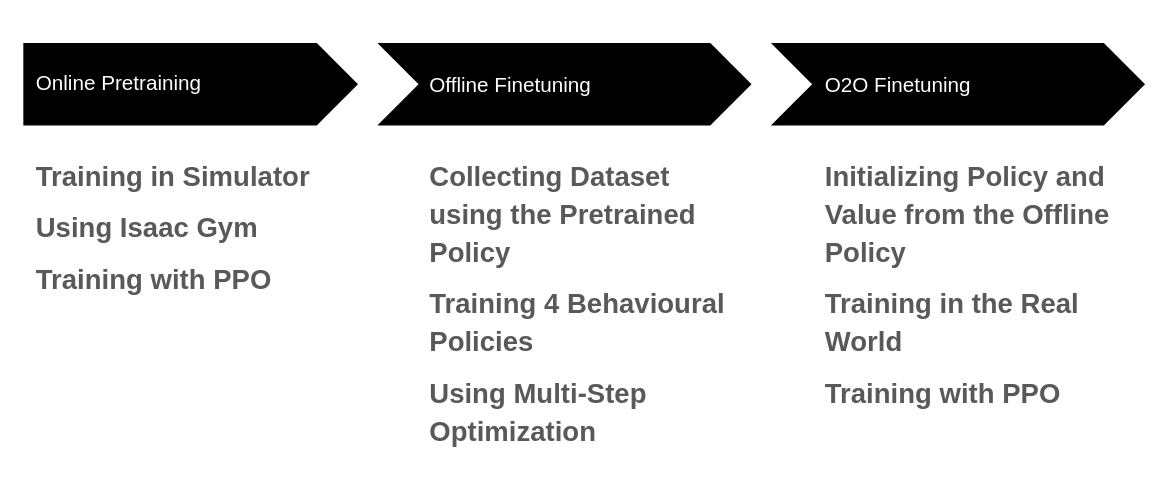
This project implements and adapts the UNI-O4 framework on the Unitree Aliengo platform, focusing on sim-to-real legged robotics, real-world policy deployment, and system-level integration.
The implementation organizes the Aliengo hardware interface, Unitree SDK communication, RealSense T265 tracking, motion capture tools, offline data collection, simulation pretraining, and PPO-based real-world training into a modular deployment pipeline.
This project implements preview control for Center of Mass and Zero Moment Point regulation to improve bipedal walking stability. It generates stable walking trajectories by planning ZMP references and computing corresponding CoM motion for dynamic balance.
The system combines trajectory generation, inverse kinematics, gait generation, and PyBullet-based simulation to evaluate biped walking behavior under a control pipeline focused on balance and stability.
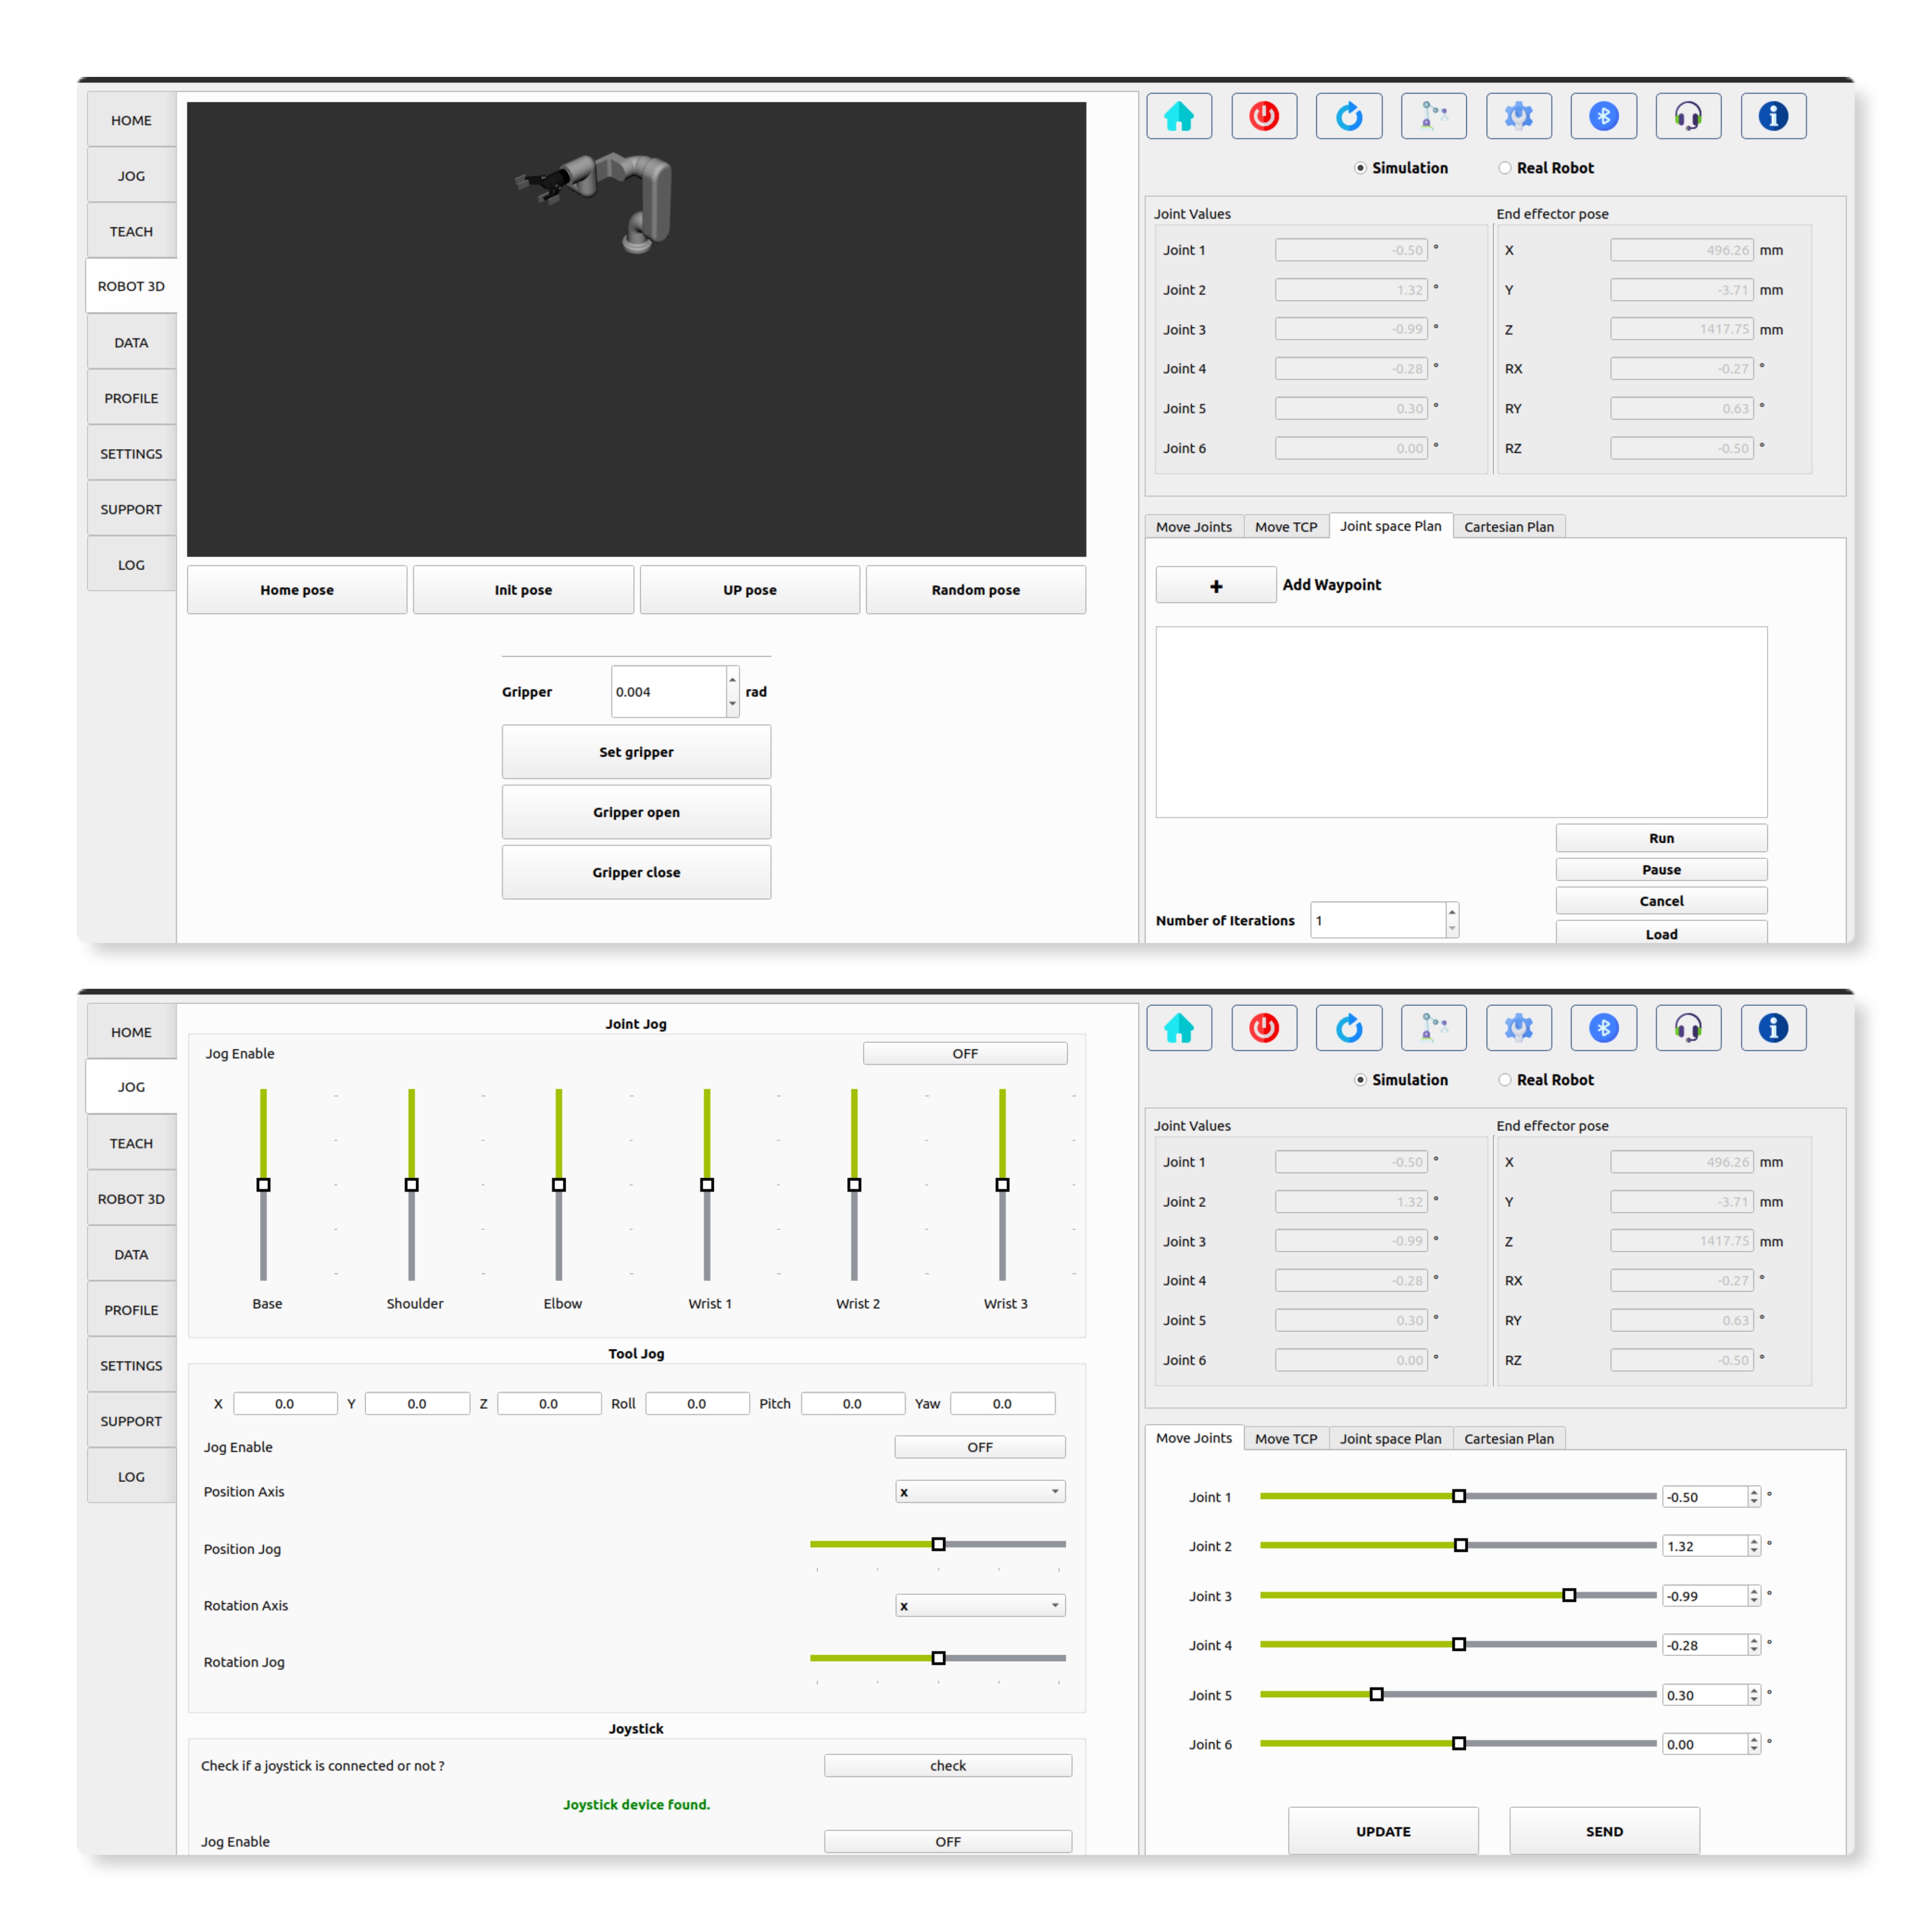
Robotic Arm Software Controller
I built a software controller for a 6-DOF robotic arm using the C++ Qt6 framework. Features included joint-based control, trajectory planning, hand teaching, gravity compensation, jogging, 3D robot visualization, and sensor data visualization. The backend used ROS and the MoveIt motion planning framework.

Object Segmentation and Clustering in Realtime 3D Point Clouds Using PCL
Realtime data from an Intel RealSense D435 camera was processed using voxel filtering, statistical outlier removal, RANSAC plane segmentation, and Euclidean clustering to locate object centroids. The detected centroids were published on a ROS publisher of type visualization_msgs/MarkerArray for pick-and-place actions using a suction gripper.

6-DOF Robotic Arm Simulation
In this project, I implemented pick-and-place using a 6-DOF robotic arm and the OctoMap framework. RGB-D sensor data was used to build a 3D model of the environment. MoveIt performed collision checking and motion planning, while objects were added to the planning scene and attached to the gripper during manipulation.
Certifications
- Advanced Robotics — Indian Institute of Technology Kanpur on NPTEL
- Aerial Robotics — University of Pennsylvania on Coursera
- Industrial Robotics — Udemy
- Reinforcement Learning Specialization — University of Alberta & Alberta Machine Intelligence Institute on Coursera
- Modern Robotics: Mechanics, Planning, and Control Specialization — Northwestern University on Coursera
Contact Me
Let’s Connect
Interested in robotics, reinforcement learning, or research collaboration?
I am open to research collaborations, robotics engineering opportunities, and discussions related to reinforcement learning, legged locomotion, hierarchical control, and sim-to-real transfer.